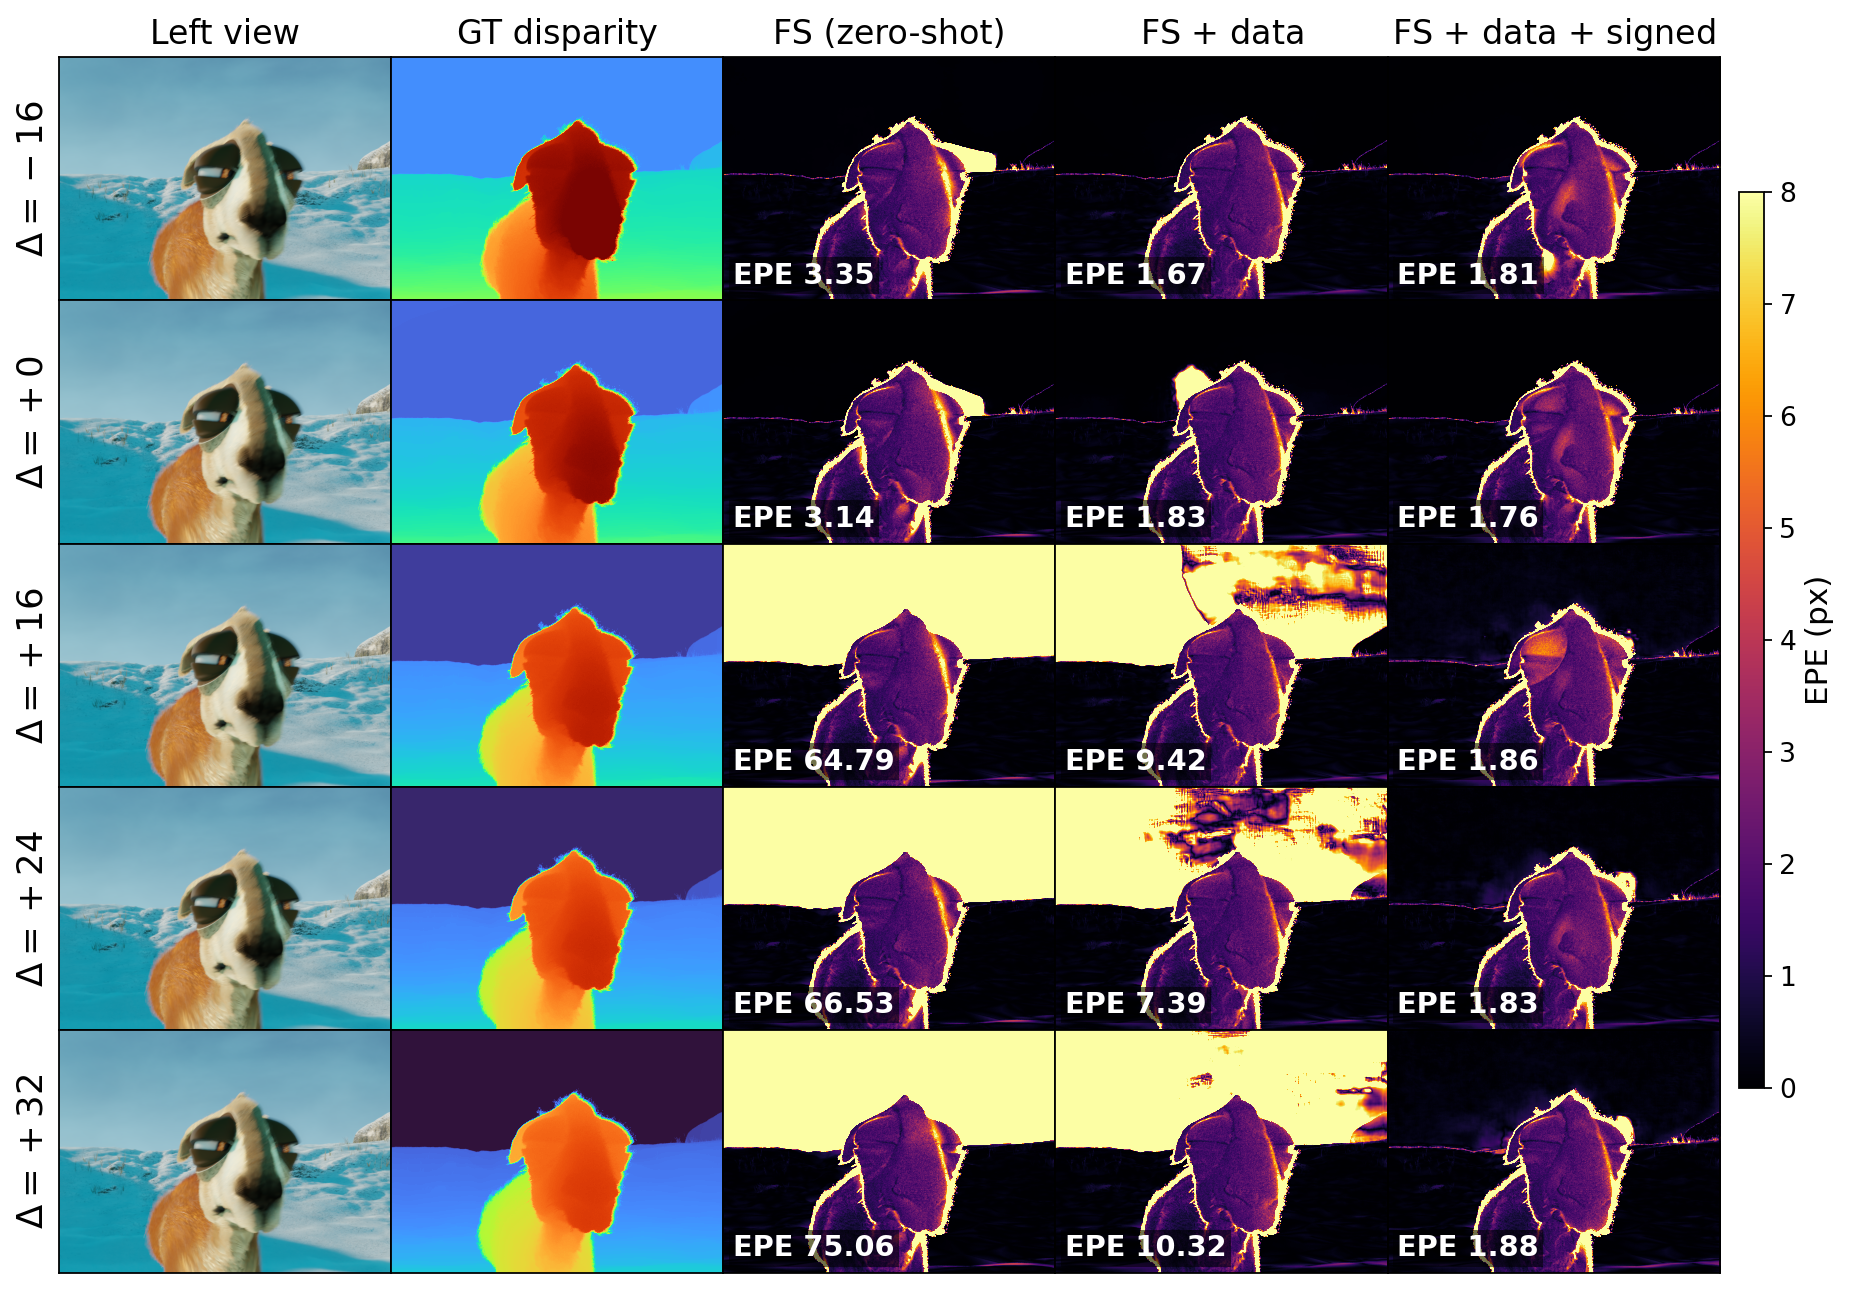
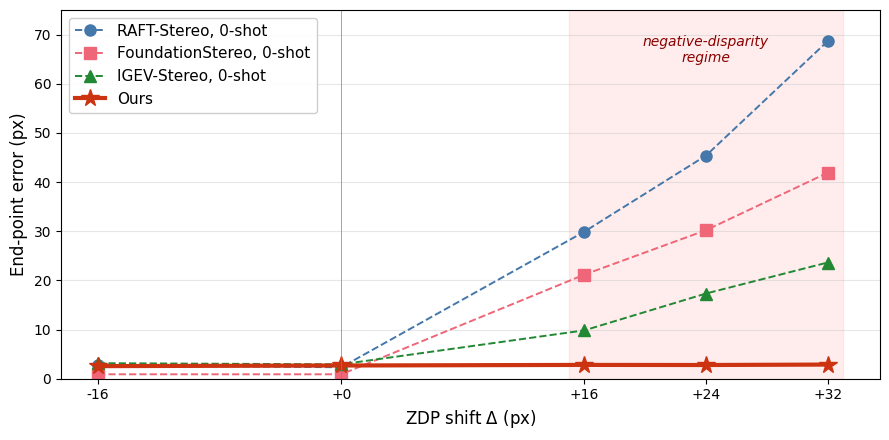
Six state-of-the-art stereo matching models collapse the moment disparity crosses zero, their error rising by 4.6โ37ร.
Stereoscopic content, from cinema 3D to VR, lives there.
Video
The blind spot
Six released backbones, three image and three video, degrade the instant disparity crosses zero: EPE reaches 13โ150 px at ฮ=+32 on identical scene content (dashed). Fine-tuned on translated SceneFlow only (solid), all six stay within 2.9โ5.2 px across the entire signed range.

The dataset
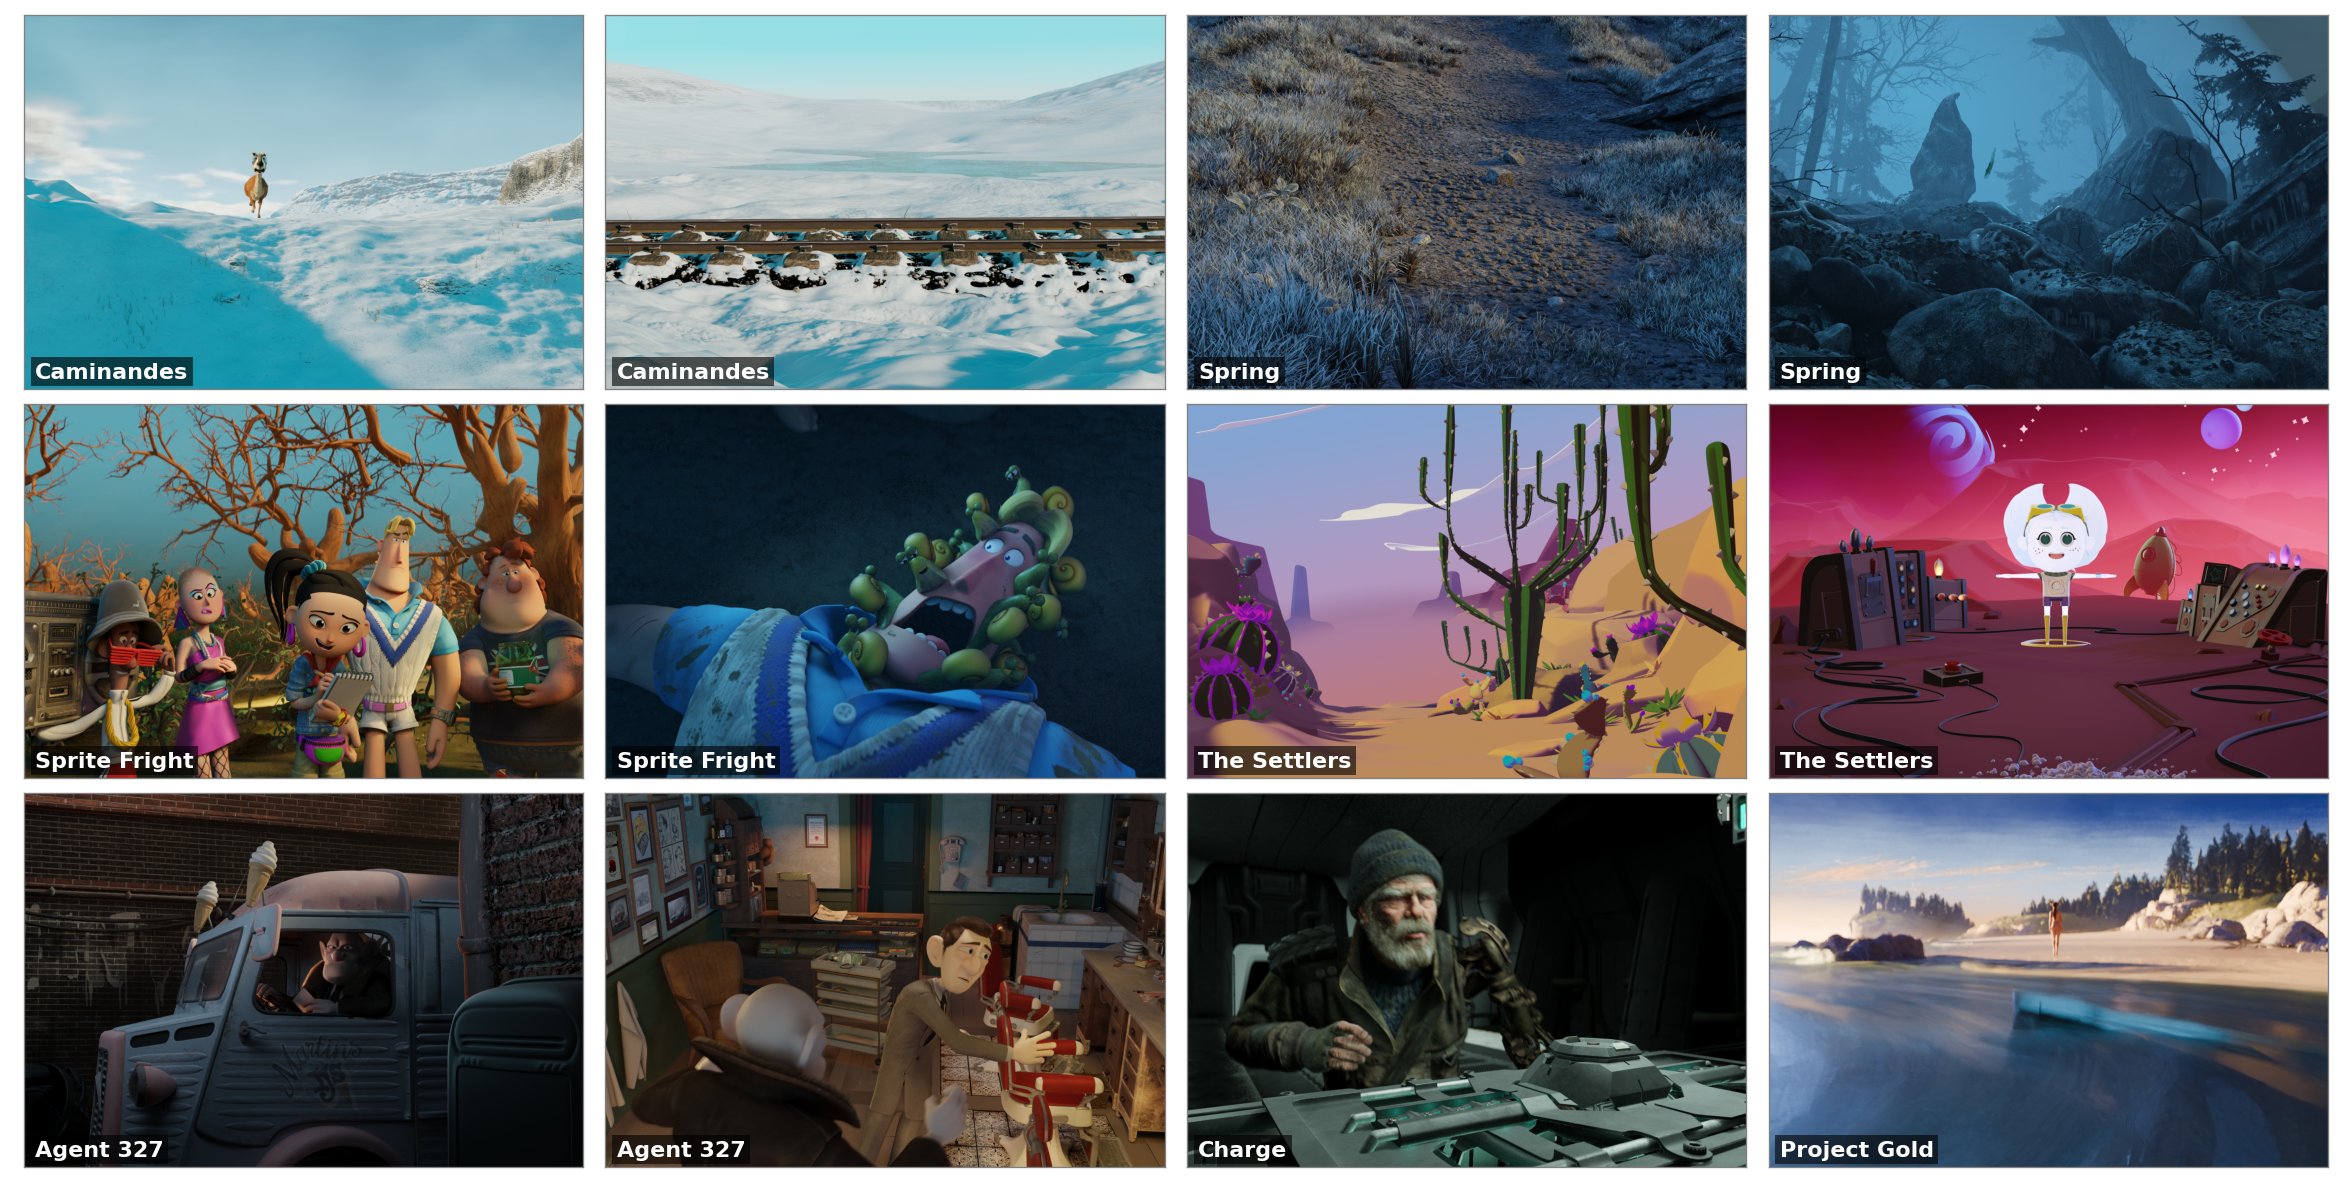
4,275 open-movie frames rendered at five zero-disparity-plane shifts each, with analytical signed ground-truth disparity. Evaluation-only: no released model trains on it.

Results
End-point error (px, native) at the hardest shift, ฮ=+32, on the full benchmark of 21,375 pairs โ 960-px inference. No model sees any benchmark data: training is horizontally translated SceneFlow only. Frozen keeps the pretrained matching features fixed and trains only the layers that read disparity out of them.
| Model | Zero-shot | + ours (full) | + ours (frozen features) |
|---|---|---|---|
| RAFT-Stereo | 149.7 | 4.68 | 4.89 |
| IGEV-Stereo | 44.9 | 3.97 | 4.06 |
| FoundationStereo | 75.3 | 2.90 | 3.01 |
| DynamicStereo | 20.8 | 5.19 | 5.19 |
| BiDAStereo | 36.2 | 4.49 | 4.51 |
| StereoAnyVideo | 13.0 | 3.98 | 4.11 |